
Back to Models

Google: Veo 3.1Active

google/veo-3.1-generate-001
CompareCreate

Veo 3.1 is Google's state-of-the-art model for generating high-fidelity, 8-second 720p, 1080p or 4k videos featuring stunning realism and natively generated audio. You can access this model programmatically using the Gemini API. To learn more about the available Veo model variants, see the Model Versions section.

By:GoogleInput Type:Output Type:Publish time:2026-01-01

Providers

Route requests across multiple providers. Copy a provider slug to set your preference.

ProviderCache Hit RateContext
Google Vertex
google-vertex
--$0.2-0.6/secondsRead:-/ M tokensWrite:-/ M tokens100K--
Uptime

Direct request success rate on AI Gateway and per-provider.

Oct 25, 21:19
Google Vertex100.00%

Throughput

P50 throughput on live AI Gateway traffic, in tokens per second (TPS).

No data
No data

Latency

P50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.

No data
No data

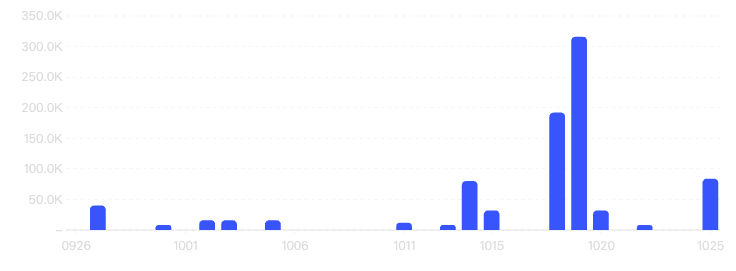
Activity

Token volume and request traffic to this model over time.

Token Consumption
Oct 25
Google Vertex84.0K

Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.

Benchmarks

Scores on standardized evaluations. Higher percentages are better — and rank percentile shows

Metrics sourced fromArtificial Analysis

No data
No benchmark data is available for this model.

Apps

Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All

Token Ranking
No data
No app usage is available for this period.

Related Models

More models from Google

Google: Gemini 4 Argon
11.60Btokens

Gemini 4 Argon is a frontier model from Google DeepMind, released on September 30, 2026. It is the first model in the Gemini 4 series and uses a new naming scheme. It is strong in coding, financial research, legal drafting, and autonomously patching cybersecurity vulnerabilities. It accepts text, image, video, and file inputs and has a 1-million-token context window. On benchmarks, it scores 77.9% on DeepSWE v1.1, ahead of Claude Opus 5.5 and GPT-6 Astra, and ranks first on the Vals Index with 68.90%.

Google: Nano Banana 2.1 (Gemini Nano Banana 2.1)
87.96Mtokens

Gemini Nano Banana 2.1 is an upgraded multimodal reasoning image model for production-grade image generation and editing, with stronger prompt adherence, multi-reference editing, and improved visual fidelity. It understands text, images, video, and PDF inputs, supports interleaved text and image generation, and can reason over complex spatial and compositional instructions before generating images. The model also supports grounding with Google Search and Google Image Search for better long-tail entity recognition, visual understanding, and output accuracy.

Gemini 3.8 Flash TTS
594.57Ktokens

Gemini 3.8 Flash TTS is a text-to-speech model from Google and the successor to Gemini 3.1 Flash TTS Preview. It is the creative tier of the 3.8 TTS family, suited for narration, character work, and multi-speaker dialogue where voice fidelity, acting nuance, and regional dialect coverage matter more than latency.