

Ling-3.0-flash is the latest-generation cost-effective model in the Ling series, with 124B total parameters, 5.1B activated parameters, a native 256K context window extendable up to 1M. Compared to the previous flash model, Ling-3.0-flash delivers significantly enhanced stability in long-horizon tasks, markedly higher tool calling accuracy, and substantially improved compatibility with common Harness environments. In coding tasks, Ling-3.0-flash features greatly optimized spatial understanding, capable of constructing physical scene grids and relative positions. Additionally, thanks to its hybrid Reasoning mode, task success rates across varying difficulty levels have all improved.
Back to Models -$0.06/ M tokens$0.18/ M tokensRead:0.012/ M tokensWrite:-/ M tokens262.14K--
 25.3%$0.06/ M tokens$0.18/ M tokensRead:0.012/ M tokensWrite:-/ M tokens262.14K--
Providers
Route requests across multiple providers. Copy a provider slug to set your preference.
ProviderCache Hit RateContext
NovitaAI
novita
Ant Ling
ant-ling
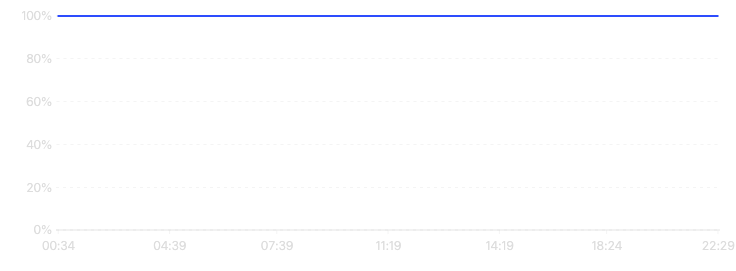
Uptime
24hoursDirect request success rate on AI Gateway and per-provider.
Oct 26, 20:14
Ant Ling100.00%
Throughput
24hoursP50 throughput on live AI Gateway traffic, in tokens per second (TPS).
No data
Latency
24hoursP50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.
No data
Activity
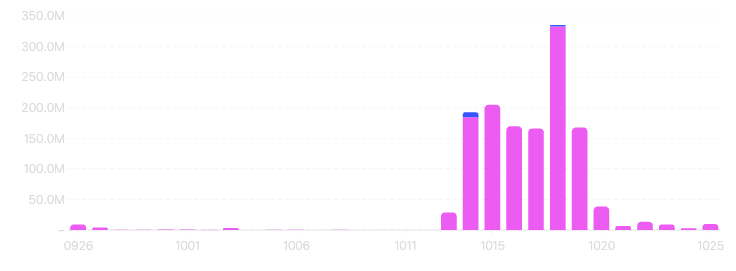
Token volume and request traffic to this model over time.
Token Consumption
Oct 25
NovitaAI-
Ant Ling10.0M
Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.
Benchmarks
Scores on standardized evaluations. Higher percentages are better — and rank percentile shows
Metrics sourced fromArtificial Analysis
 Artificial Analysis


Apps
Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All
Token Ranking
No app usage is available for this period.
Related Models
More models from inclusionAI