Back to Models

MiniMax: MiniMax M2.7Active

minimax/minimax-m2.7
CompareChat

M2.7 delivers outstanding performance in real-world software engineering, including end-to-end complete project delivery, log analysis and bug triaging, code security, machine learning, and more. On the benchmark SWE-Pro, M2.7 scores 56.22%, nearly matching the level of Opus. This capability also extends to end-to-end complete project delivery scenarios (VIBE-Pro 55.6%) and deep understanding of complex engineering systems on Terminal Bench 2 (57.0%).

In the professional office domain, we have improved the model's specialized knowledge and task delivery capabilities across various fields. On GDPval-AA, its ELO score is 1495, the highest among open-source models. M2.7's ability to perform complex editing in the Office suite (Excel/PPT/Word) has significantly improved, enabling better multi-round revisions and high-fidelity editing. M2.7 is capable of interacting with complex environments. Across 40 complex skills (> 2000 tokens) cases, M2.7 still maintains a 97% skill adherence rate. In OpenClaw usage, M2.7 has shown significant improvement compared to M2.5, scoring close to the latest Sonnet 4.6 in the MMClaw evaluation.

M2.7 possesses excellent identity retention capabilities and emotional intelligence. Beyond productivity use cases, it also opens up space for innovation in interactive entertainment scenarios.

By:MiniMaxInput Type:Output Type:Publish time:2026-03-18

Providers

Route requests across multiple providers. Copy a provider slug to set your preference.

ProviderCache Hit RateContext
Streamlake
streamlake
33.9%$0.3/ M tokens$1.2/ M tokensRead:0.06/ M tokensWrite:0.375/ M tokens204.8K7.78s15.6tps
MiniMax
minimax
26.4%$0.3/ M tokens$1.2/ M tokensRead:0.06/ M tokensWrite:0.375/ M tokens204.8K--
TencentCloud
tencent-cloud
-$0.3/ M tokens$1.2/ M tokensRead:0.06/ M tokensWrite:-/ M tokens204.8K--

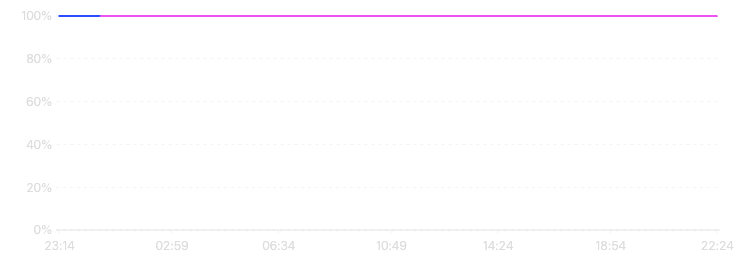
Uptime

Direct request success rate on AI Gateway and per-provider.

Oct 26, 00:24
Streamlake100.00%
MiniMax100.00%

Throughput

P50 throughput on live AI Gateway traffic, in tokens per second (TPS).

Oct 26, 15:00
Streamlake15.6 tps

Latency

P50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.

Oct 26, 15:00
Streamlake7.78s

Activity

Token volume and request traffic to this model over time.

Token Consumption
Oct 25
Streamlake13.7K
MiniMax1.2K
TencentCloud-

Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.

Benchmarks

Scores on standardized evaluations. Higher percentages are better — and rank percentile shows

Metrics sourced fromArtificial Analysis

Apps

Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All

Token Ranking

Related Models

More models from MiniMax