Back to Models

OpenAI: o4 MiniActive

openai/o4-mini
CompareChat

OpenAI o4-mini is a compact reasoning model in the o-series, optimized for fast, cost-efficient performance while retaining strong multimodal and agentic capabilities. It supports tool use and demonstrates competitive reasoning and coding performance across benchmarks like AIME (99.5% with Python) and SWE-bench, outperforming its predecessor o3-mini and even approaching o3 in some domains.

Despite its smaller size, o4-mini exhibits high accuracy in STEM tasks, visual problem solving (e.g., MathVista, MMMU), and code editing. It is especially well-suited for high-throughput scenarios where latency or cost is critical. Thanks to its efficient architecture and refined reinforcement learning training, o4-mini can chain tools, generate structured outputs, and solve multi-step tasks with minimal delay—often in under a minute.

By:OpenAIInput Type:Output Type:Publish time:2025-04-16

Providers

Route requests across multiple providers. Copy a provider slug to set your preference.

ProviderCache Hit RateContext
Azure
azure
-$1.1/ M tokens$4.4/ M tokensRead:0.28/ M tokensWrite:-/ M tokens200K--
OpenAISunset
openai
-$1.1/ M tokens$4.4/ M tokensRead:0.275/ M tokensWrite:-/ M tokens200K--

Uptime

Direct request success rate on AI Gateway and per-provider.

No data
No data

Throughput

P50 throughput on live AI Gateway traffic, in tokens per second (TPS).

No data
No data

Latency

P50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.

No data
No data

Activity

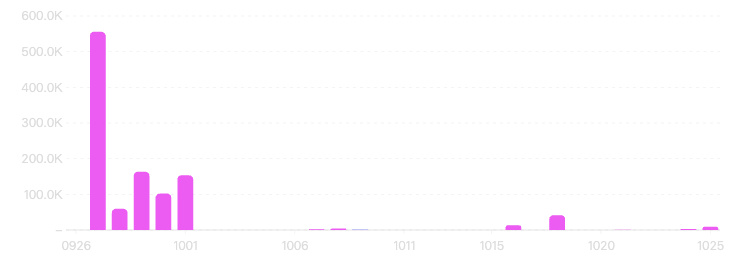
Token volume and request traffic to this model over time.

Token Consumption
Oct 25
OpenAI-
Azure9.3K

Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.

Benchmarks

Scores on standardized evaluations. Higher percentages are better — and rank percentile shows

Metrics sourced fromArtificial Analysis

Apps

Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All

Token Ranking

Related Models

More models from OpenAI

OpenAI: GPT-6.1 Sol
71.70Btokens

GPT-6.1 Sol is a production-grade OpenAI model designed for agentic workloads, optimized for long-horizon and multi-step tasks such as continuous tool use, complex coding, computer use, and professional workflows. It delivers capabilities approaching GPT-6 Astra at significantly lower cost, including especially low cached-input pricing that makes it well suited for reusable-context agent systems and enterprise deployment scenarios.

OpenAI: GPT-6 Luna
92.81Btokens

GPT-6 Luna is the fast, cost-efficient model in OpenAI's GPT-6 series, positioned below GPT-6 Sol. It is suited for high-volume and latency-sensitive workloads such as chat, classification, and lightweight agentic tasks, and at higher reasoning effort it can take on complex software engineering and computer-use tasks that previously called for a Sol-tier model. It shares the GPT-6 family's gains in factual reliability and its clearer, more concise communication style.

OpenAI: GPT-6 Sol
28.42Btokens

GPT-6 Sol is the cost-efficient high-end model in OpenAI's GPT-6 series, positioned below the flagship GPT-6 Astra and above the fast GPT-6 Luna tier. It is suited for demanding professional work, agentic coding, business workflow automation, and computer use, and is particularly strong at long-horizon software engineering tasks in real codebases. It approaches Astra-level factual reliability at a much lower cost and shares Astra's clearer, more concise communication style in technical and coding conversations.