
GPT-4.1 Mini is a mid-sized model delivering performance competitive with GPT-4o at substantially lower latency and cost. It retains a 1 million token context window and scores 45.1% on hard instruction evals, 35.8% on MultiChallenge, and 84.1% on IFEval. Mini also shows strong coding ability (e.g., 31.6% on Aider’s polyglot diff benchmark) and vision understanding, making it suitable for interactive applications with tight performance constraints.
Back to Models -$0.4/ M tokens$1.6/ M tokensRead:0.1/ M tokensWrite:-/ M tokens1.05M--
 25.4%$0.4/ M tokens$1.6/ M tokensRead:0.1/ M tokensWrite:-/ M tokens1.05M1.13s80.7tps
Providers
Route requests across multiple providers. Copy a provider slug to set your preference.
ProviderCache Hit RateContext
OpenAI
openai
Azure
azure
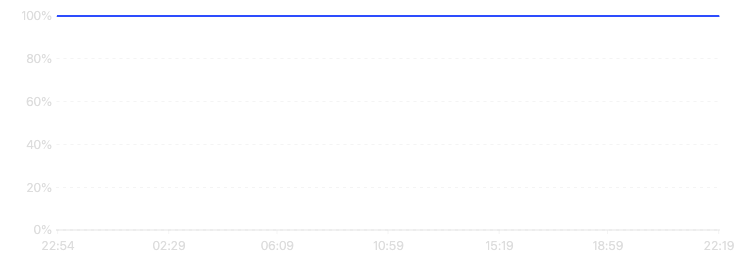
Uptime
24hoursDirect request success rate on AI Gateway and per-provider.
Oct 26, 20:14
Azure100.00%
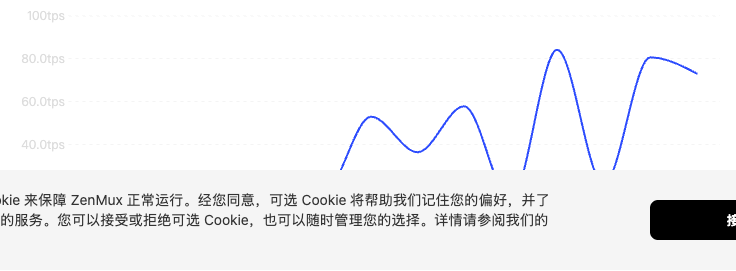
Throughput
24hoursP50 throughput on live AI Gateway traffic, in tokens per second (TPS).
Oct 26, 18:00
Azure80.7 tps
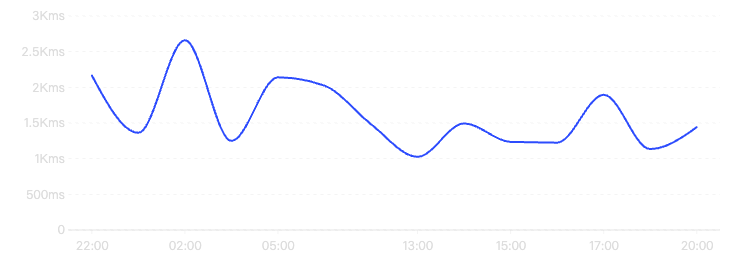
Latency
24hoursP50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.
Oct 26, 18:00
Azure1.13s
Activity
Token volume and request traffic to this model over time.
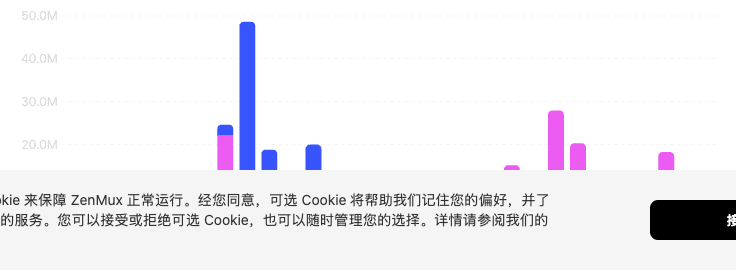
Token Consumption
Oct 25
OpenAI-
Azure2.0M
Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.
Benchmarks
Scores on standardized evaluations. Higher percentages are better — and rank percentile shows
Metrics sourced fromArtificial Analysis
 Artificial Analysis


Apps
Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All
Token Ranking


Related Models
More models from OpenAI