Ling 3.1 Flash is a hybrid reasoning mixture-of-experts model from inclusionAI, with 25B active parameters out of 560B total.
We use essential cookies to keep OpenQiao working. With your permission, optional cookies help us remember your preferences and understand how you use our services. You can accept or reject optional cookies, or manage your choices at any time. Learn more in our Privacy Policy.


Ant Ling Provider
Models provided by Ant LingTerm of Service
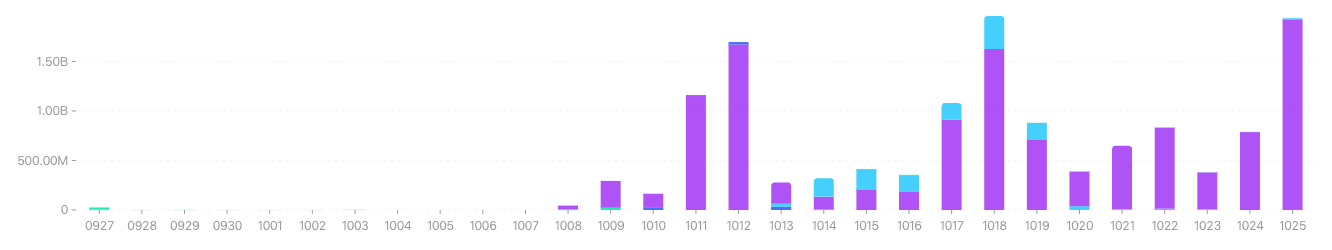
Models · 6

inclusionAI: Ling-3.1-flash
inclusionai/ling-3.1-flash
12.16Btokens
83.68%Cache Hit Rate
Input Type
Output Type
Input$0/M tokens
Output$0/M tokens
Context-
Max Output-
Available on 1 provider
inclusionAI: Ling-3.0-flash
inclusionai/ling-3.0-flash
20.79Btokens
86.57%Cache Hit Rate
Ling-3.0-flash is the latest-generation cost-effective model in the Ling series, with 124B total parameters, 5.1B activated parameters, a native 256K context window extendable up to 1M. Compared to the previous flash model, Ling-3.0-flash delivers significantly enhanced stability in long-horizon tasks, markedly higher tool calling accuracy, and substantially improved compatibility with common Harness environments. In coding tasks, Ling-3.0-flash features greatly optimized spatial understanding, capable of constructing physical scene grids and relative positions. Additionally, thanks to its hybrid Reasoning mode, task success rates across varying difficulty levels have all improved.
Input Type
Output Type
Input$0.06/M tokens
Output$0.18/M tokens
Context-
Max Output-
Available on 1 provider
inclusionAI: Ling-3.0-flash-VL
inclusionai/ling-3.0-flash-vl
193.06Mtokens
45.42%Cache Hit Rate
Ling 3.0 Flash VL builds on Ling 3.0 Flash (124B total / 5.5B active MoE from InclusionAI), further strengthening its language capabilities while adding native visual perception and advanced visual agent capabilities. Hybrid instant/reasoning model with tool calling.
Input Type
Output Type
Input$0.075/M tokens
Output$0.22/M tokens
Context-
Max Output-
Available on 1 provider
inclusionAI: Ling-2.6-1T
inclusionai/ling-2.6-1t
5.02Btokens
75.83%Cache Hit Rate
56% OFF
Sunset: ant-ling:2026/11/15
Ring-2.6-1T is a 1T-parameter-scale thinking model with 63B active parameters, built for real-world agent workflows that require both strong capability and operational efficiency. It is optimized for coding agents, tool use, and long-horizon task execution, delivering leading results on benchmarks including PinchBench, ClawEval, TAU2-Bench, and GAIA2-search.
With adaptive reasoning effort across high and xhigh modes, Ring-2.6-1T dynamically allocates reasoning budget based on task complexity. This enables stronger performance with lower token overhead, especially in tool-heavy and multi-turn agent workflows.
Ring-2.6-1T is designed for advanced coding agents, complex reasoning pipelines, and large-scale autonomous systems where execution quality, latency, and cost efficiency all matter.
Input Type
Output Type
Input$0.1318155/M tokens
Output$1.0984625/M tokens
Context-
Max Output-
Available on 1 provider
inclusionAI: Ling-2.6-flash
inclusionai/ling-2.6-flash
33.04Mtokens
75.47%Cache Hit Rate
Sunset: ant-ling:2026/11/15
Ling-2.6-flash is a 100B-parameter text model focused on intelligence efficiency, delivering strong performance while minimizing token usage. It supports a 256K context window with up to 32K output tokens, function calling, structured output, and prompt caching. It is particularly well-suited for code completion and debugging, rapid document processing, and lightweight agent interactions.
Input Type
Output Type
Input$0.1/M tokens
Output$0.3/M tokens
Context-
Max Output-
Available on 1 provider
inclusionAI: Ring-2.6-1T
inclusionai/ring-2.6-1t
949.91Mtokens
68.99%Cache Hit Rate
56% OFF
Sunset: ant-ling:2026/11/15
Ring-2.6-1T is a 1T-parameter-scale thinking model with 63B active parameters, built for real-world agent workflows that require both strong capability and operational efficiency. It is optimized for coding agents, tool use, and long-horizon task execution, delivering leading results on benchmarks including PinchBench, ClawEval, TAU2-Bench, and GAIA2-search.
With adaptive reasoning effort across high and xhigh modes, Ring-2.6-1T dynamically allocates reasoning budget based on task complexity. This enables stronger performance with lower token overhead, especially in tool-heavy and multi-turn agent workflows.
Ring-2.6-1T is designed for advanced coding agents, complex reasoning pipelines, and large-scale autonomous systems where execution quality, latency, and cost efficiency all matter.
Input Type
Output Type
Input$0.1318155/M tokens
Output$1.0984625/M tokens
Context-
Max Output-
Available on 1 provider