

GLM-5.2 supports a larger context window and output length, with up to 1M context and 128K output tokens. It adds streaming output for tool calls via tool_stream=true, enabling real-time access to tool call arguments. Like the GLM-4.7 series, it supports deep thinking with thinking={ type: "enabled" }, where thinking is enforced once enabled, and introduces reasoning_effort to control reasoning intensity under chain-of-thought mode. It also delivers stronger coding performance and more advanced reasoning capabilities.
Back to Models -$1.4/ M tokens$4.4/ M tokensRead:0.28/ M tokensWrite:0.0025/ M tokens1M--
 74.1%$1.4/ M tokens$4.4/ M tokensRead:0.14-0.28/ M tokensWrite:1.75/ M tokens1M3.29s26.8tps
 -$1.4/ M tokens$4.4/ M tokensRead:0.26/ M tokensWrite:-/ M tokens1M--
 37.5%$1.4/ M tokens$4.4/ M tokensRead:0.26/ M tokensWrite:-/ M tokens1M2.06s44.9tps
 -$1.4/ M tokens$4.4/ M tokensRead:0.28/ M tokensWrite:-/ M tokens1M1.92s32.1tps
 14.6%$1.4/ M tokens$4.4/ M tokensRead:0.26/ M tokensWrite:-/ M tokens1M1.61s43.0tps
Providers
Route requests across multiple providers. Copy a provider slug to set your preference.
ProviderCache Hit RateContext
Volcengine
volcengine
Alibaba Cloud
alibaba
Streamlake
streamlake
Baidu
baidu
TencentCloud
tencent-cloud
BigModel
bigmodel
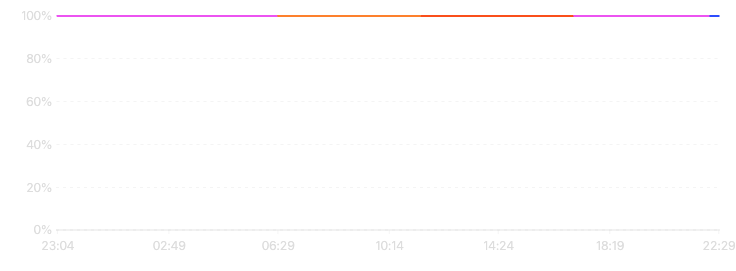
Uptime
24hoursDirect request success rate on AI Gateway and per-provider.
Oct 26, 20:04
Alibaba Cloud100.00%
Baidu100.00%
TencentCloud-
BigModel-
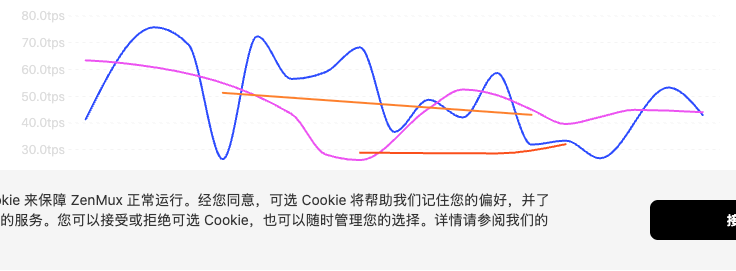
Throughput
24hoursP50 throughput on live AI Gateway traffic, in tokens per second (TPS).
Oct 26, 19:00
Alibaba Cloud-
Baidu44.9 tps
TencentCloud-
BigModel-
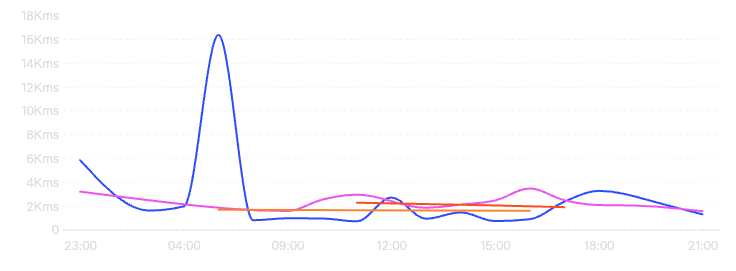
Latency
24hoursP50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.
Oct 26, 19:00
Alibaba Cloud-
Baidu2.06s
TencentCloud-
BigModel-
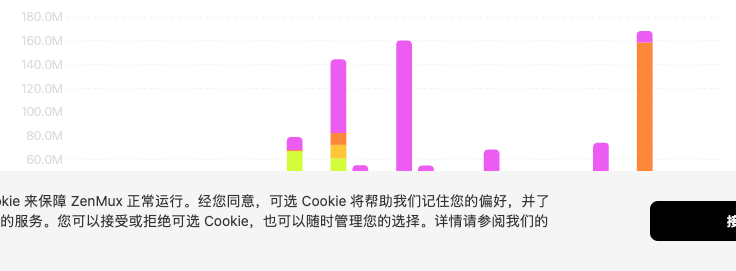
Activity
Token volume and request traffic to this model over time.
Token Consumption
Oct 25
Volcengine-
Alibaba Cloud23.1M
Streamlake-
Baidu906.0K
TencentCloud-
BigModel224.3K
Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.
Benchmarks
Scores on standardized evaluations. Higher percentages are better — and rank percentile shows
Metrics sourced fromArtificial Analysis
 Artificial Analysis


Apps
Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All
Token Ranking


Related Models
More models from Z.ai