

Qwen3.8-Flash is the latest multimodal model from the Qwen family, combining powerful reasoning and generation with remarkable speed. It natively supports a million-token context window, allowing it to process lengthy documents, entire codebases, and complex conversations in a single pass. It shines in coding assistance, agentic workflows, and visual understanding — whether it's fixing code autonomously, operating desktop applications, or analyzing charts and long videos. Fully compatible with both OpenAI and Anthropic API protocols, it integrates seamlessly with popular developer tools like Claude Code and Codex, making it easy to build high-concurrency applications and intelligent workflows. With strong performance and highly competitive inference costs, Qwen3.8-Flash is an ideal choice for developers and businesses seeking the best of both worlds in AI applications.
Providers
Route requests across multiple providers. Copy a provider slug to set your preference.

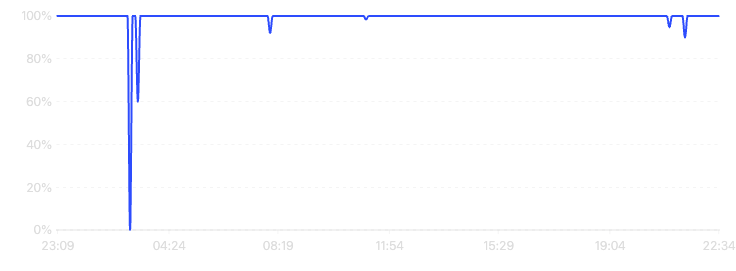
Uptime
24hoursDirect request success rate on AI Gateway and per-provider.
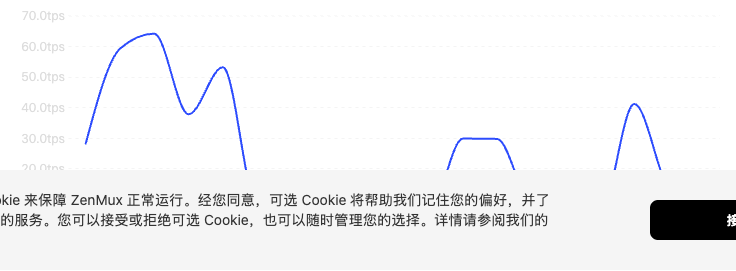
Throughput
24hoursP50 throughput on live AI Gateway traffic, in tokens per second (TPS).
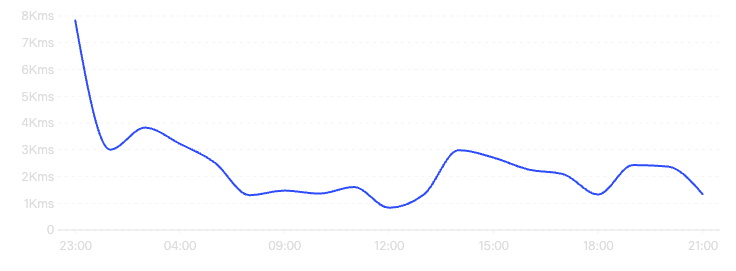
Latency
24hoursP50 time to first token (TTFT) on live AI Gateway traffic, in milliseconds.
Activity
Token volume and request traffic to this model over time.
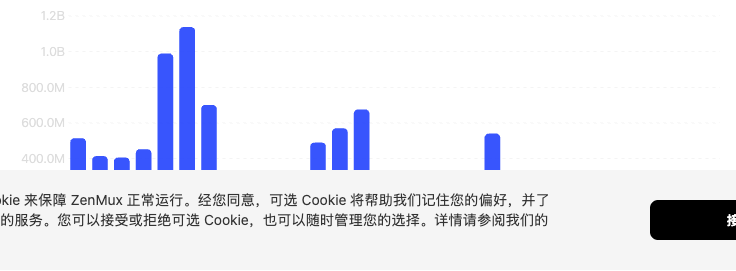
Token volume broken down by the provider that served each request. Larger segments indicate providers handling more of this model's traffic.
Benchmarks
Scores on standardized evaluations. Higher percentages are better — and rank percentile shows
Metrics sourced fromArtificial Analysis
 Artificial Analysis


Apps
Public apps that send the most traffic to this model. Good signal for what real production workloads look like — and a hint at which use cases this model is best suited for. View All


Related Models
More models from Qwen